AI-based real-time speech separation on edge devices for noisy industrial environments.
VoxFocus
New on Amplifa
About VoxFocus
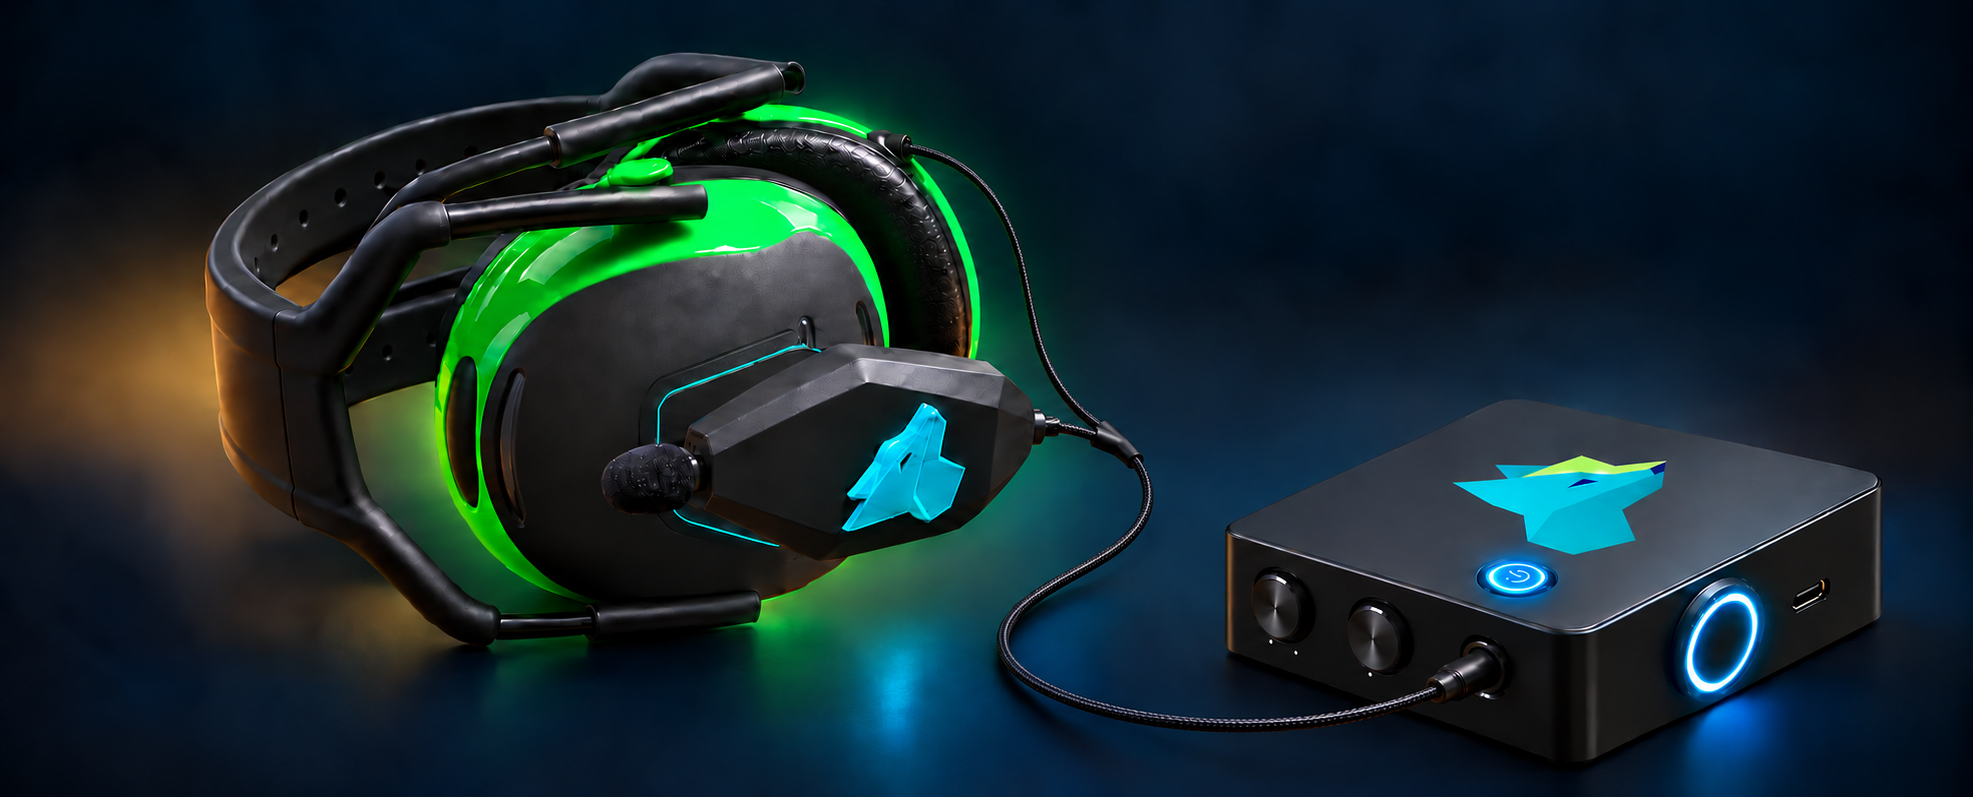
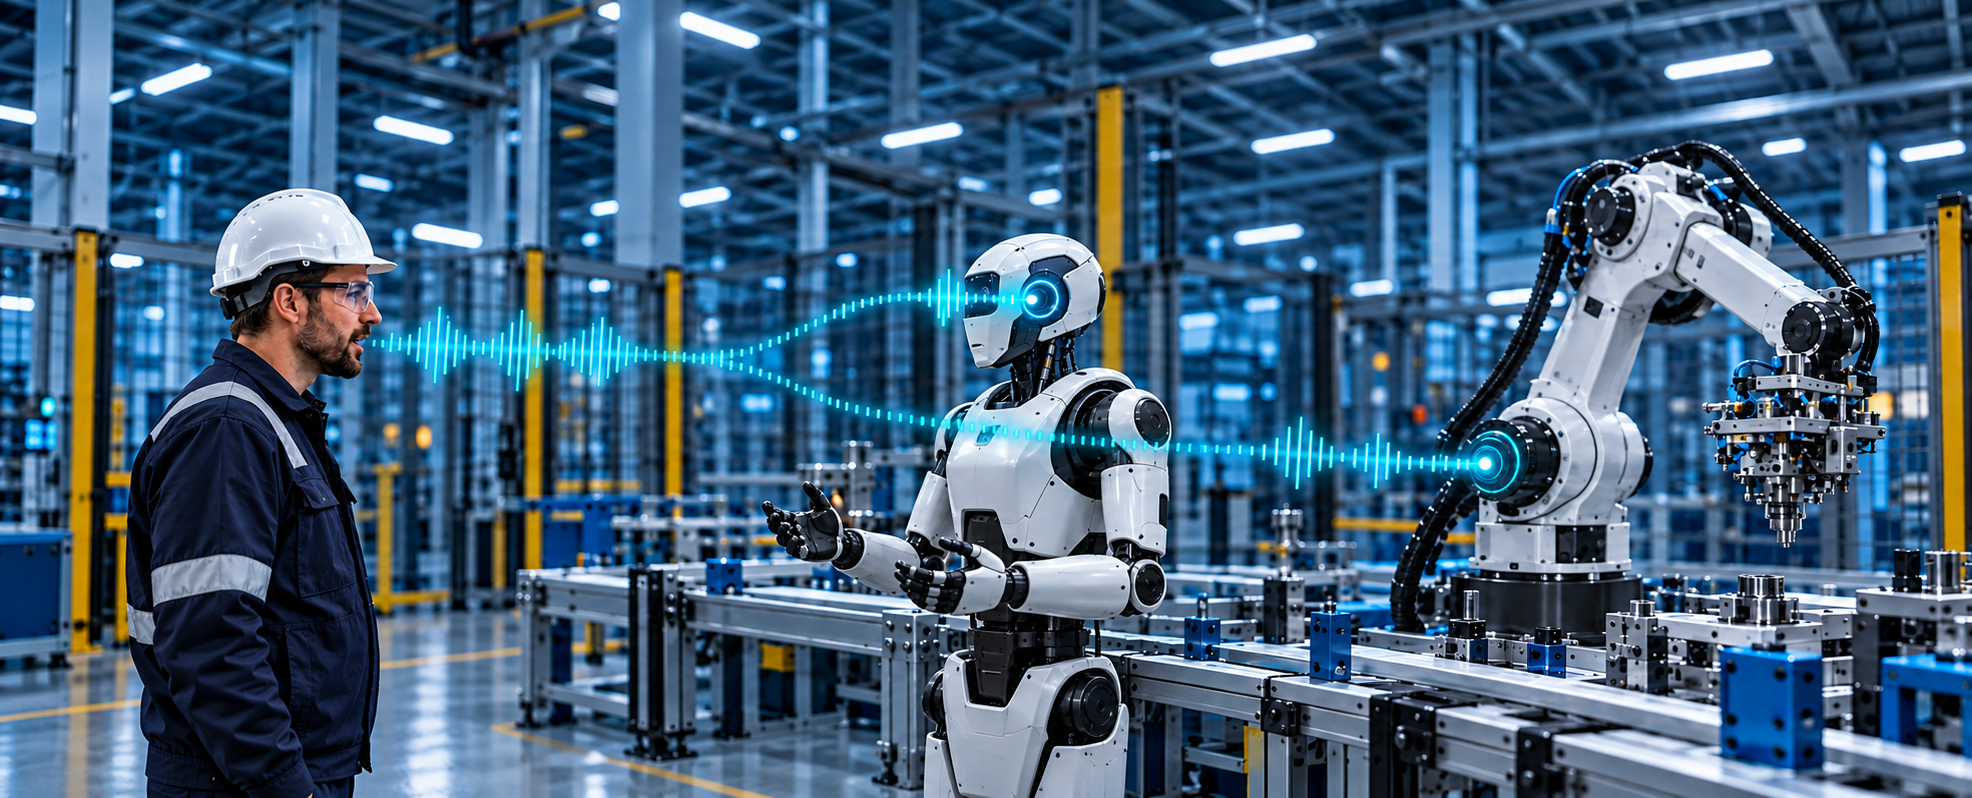
VoxFocus develops an AI-based audio platform for speech separation: the AI Audio Core separates relevant speech in real time from machine, tool and ambient noise before the signal reaches the ear or digital speech processing systems. Processing takes place locally on edge devices, i.e. without a permanent cloud connection. Two product lines emerge from this common core: COMMAND is a communication layer for hearing protection (hub plus exciter, prototype), while SENSE serves as an acoustic front-end integration for speech recognition, HMI systems and robotics. Target industries include manufacturing, mechanical engineering, robotics, system integration as well as hearing protection and occupational safety. Performance is validated in laboratory and field tests covering speech intelligibility, latency, word error rate and robustness. VoxFocus emerged from a karaoke experiment for separating voice and music and is built on four years of research and development.
- Processes
- AI-based real-time speech separation on edge devices, AI Audio Core for noisy environments, COMMAND: communication layer for hearing protection (hub + exciter, prototype), SENSE: acoustic front-end integration for speech recognition, HMI and robotics, Laboratory and field tests (speech intelligibility, latency, word error rate), Software and module integration for partner products
- Materials
- AI Audio Core (edge processing), COMMAND – communication layer for hearing protection, SENSE – acoustic front-end
- Industries
- Industry/Manufacturing, Mechanical engineering, Robotics, System integration, Hearing protection/Occupational safety, Assistive hearing systems
- 01
Signal acquisition (microphone)
- 02
AI Audio Core: speech separation on edge devices
- 03
Delivery to the human (COMMAND) or to a speech system (SENSE)
- 04
Laboratory and field tests
- 05
Software and module integration for partner products
Technology & Processes
AI Audio Core (edge processing)
Local, real-time-capable speech separation without a permanent cloud connection.
COMMAND – communication layer for hearing protection
Prototype consisting of hub, exciter and specified hearing protection for noisy workplaces.
SENSE – acoustic front-end
Preparation of speech for existing speech recognition, HMI and robotics.
Products & Applications
Inside the production
Industries
Additional services
History
- ~2021
Started as a karaoke experiment for separating voice and music during the pandemic; four years of research & development
- 2024
First place in the Rhineland-Palatinate ideas competition (Mainz region, maturity level 1)
- 2025
Top 50 in the start-up competition – Digital Innovations (Winter 2025)
- 2025
AI Founder Fellowship (MISSION KI)
- 2025
Funding through the AI NATION grant program